Control plane
Persistent
Python + PostgreSQL own durable conversations, projects, preferences, policy, audit and system state.
Private local AI system
A persistent, local-first personal AI system built so that identity, memory, permissions and project context survive even when the underlying model or inference machine changes.
The problem
I wanted one private assistant that could retain project context, study work, homelab knowledge, preferences and operating history without turning a single model checkpoint into the source of truth.
That led to a system architecture where models are replaceable execution capabilities. Durable identity, memory, permissions, tasks, audit and policy remain under the Core and PostgreSQL control plane.
Architecture
Public diagram is intentionally sanitized: internal addressing, credentials and low-level network topology are omitted.
Implemented evidence
Control plane
Python + PostgreSQL own durable conversations, projects, preferences, policy, audit and system state.
Inference
A dedicated inference worker serves replaceable local models while Ollama remains private to the worker.
Evaluation
A fixed local model tournament compared quality, latency, memory pressure and structured-output behavior.
Model policy
Five exact-digest model roles separate interactive, fallback, heavy reasoning, coding and slow-path use.
Transport
The control plane reaches the inference worker through a narrowly scoped authenticated transport rather than a broad model API.
Client
The native foreground Android client source is merged and being rebuilt chat-first; it uses canonical Core sessions, AndroidKeyStore device proof and explicit tap/PTT voice. Signed physical-device acceptance remains a separate gate.
Evaluation
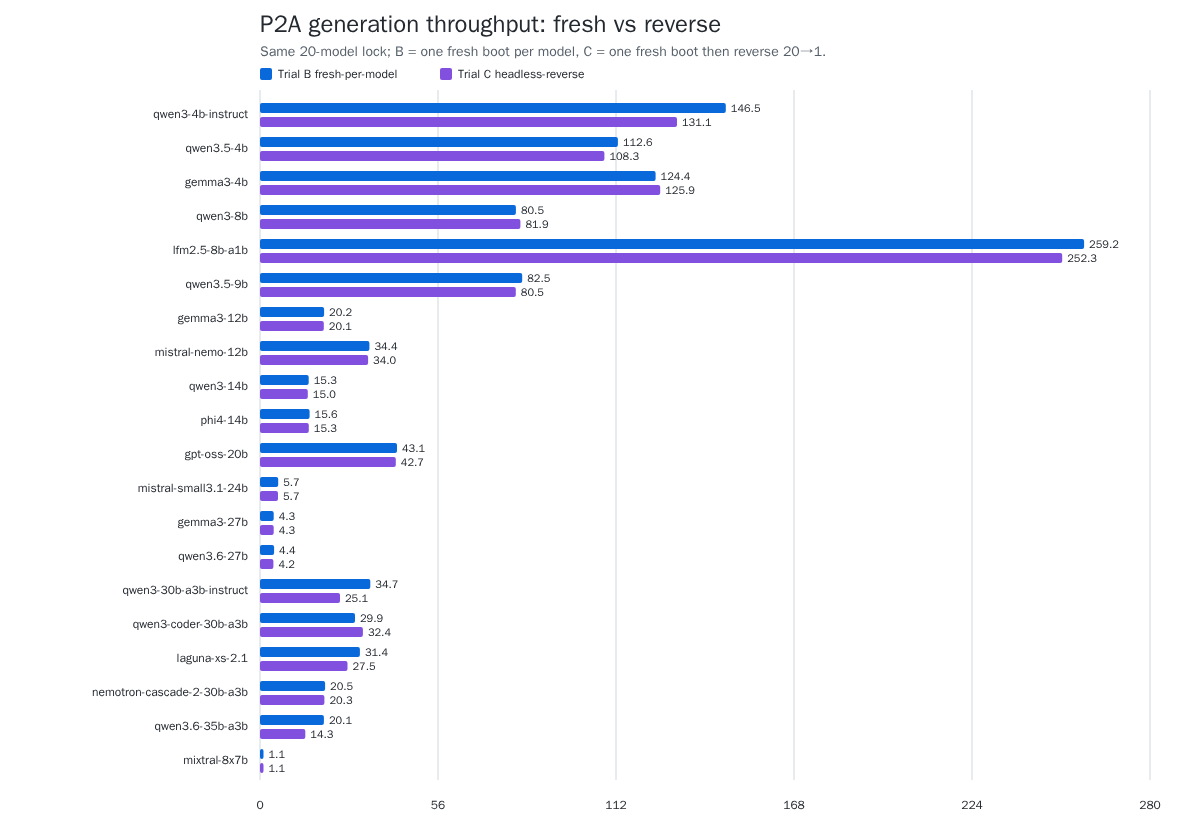
The benchmark compared more than raw generation speed. It tracked semantic quality, structured-output behavior, preload cost, GPU residency, host-memory pressure, swap and sustained responsiveness.
The result was deliberately not “pick the highest score.” ROS uses a role-based policy because the fastest interactive model, stronger heavy-reasoning models and the slowest maximum-quality candidate occupy different points on the local quality/latency/resource frontier.
Real benchmark evidence
This is a repository-tracked comparison from the historical Work1 evaluation lane. The production inference executor later moved to a dedicated GPU VM, but the measured tournament remains the evidence base that shaped the role policy.
Key decisions
Changing facts, project state, preferences and permissions live in structured durable state. Models remain replaceable computation.
Inference nodes, storage and tools do not become separate personalities. ROS keeps one persistent identity while capabilities remain separately permissioned.
Assistant, code, ops, database, deployment and file capabilities are deliberately separated. Owner recovery authority is not handed to ROS.
Model and hardware decisions are made from measured quality, latency and resource behavior on actual hardware instead of theoretical specifications.
Private memory and prompts remain local by default. Degraded local capability is reported honestly instead of silently routing private work elsewhere.
The Android client deliberately avoids always-on listening, background capture and hidden audio persistence. Text remains available when voice degrades.
Current client direction
The Android client source is merged and is being rebuilt as a chat-first native foreground app. It connects to the same canonical Core conversations and device authority rather than maintaining a mobile shadow store.
Device proof uses a non-exportable key in AndroidKeyStore. Voice is explicit tap/PTT input, requests microphone permission only when invoked, and does not introduce a wake phrase, background microphone, hidden cloud fallback or raw audio archive.
What I owned
AI-assisted workflow
I use ChatGPT and Codex extensively for implementation, research, debugging, audits and documentation. My role is to define the product and architecture, set constraints and acceptance criteria, make trade-offs and verify the resulting system through tests, CI and live operational evidence.
Current limitations
ROS is a private local-runtime system, not a public SaaS or hyperscale service. Current inference is bounded by a single local GPU, one active generation at a time and an evidence-backed 4096-token context policy; larger-context or concurrent operation requires new evidence.
The Android client remains in active product-finish work, with signed physical-device acceptance separate from source acceptance. Fine-tuning, broad autonomous operations and silent cloud fallback remain intentionally out of scope.
Stack / delivery
Core
Durable conversations, projects, preferences, policy, provenance and audit remain outside model weights.
Inference
Exact-digest local model roles run behind a dedicated worker instead of exposing a general-purpose model API.
Security
TLS 1.3 mTLS protects the inference path; device trust and capability authority remain separately bounded.
Delivery
Runtime changes are tied to tested source identity, host evidence, explicit acceptance and a retained rollback path.
Honest boundary
ROS is evidence of applied AI systems engineering, local inference, model evaluation, persistent-state architecture, security boundaries and product integration.
It is not evidence that I train foundation models, operate hyperscale GPU clusters, or solved general autonomous-agent safety. Fine-tuning is deliberately deferred until stable interaction evidence justifies it.
Next case study